Get the latest gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
A Benchmark That Refuses to Hand Out Zeros — or Easy 100s
Most AI leaderboards have a dirty secret: they measure how well a model chats, not how well it works. Firmulate, an AI company emulator that runs frontier models as actual businesses, took a different approach — and one design decision is turning heads. When a model does absolutely nothing — no decisions, no crisis response, no deals — it still scores 26 points out of 100.
That’s not a bug. It’s a philosophy. And it says a lot about what honest AI evaluation should look like as agents start touching real CRMs, support queues, and forecasts.
As an affiliate, we earn on qualifying purchases.
The Experiment: Same Company, Same Worst Week
Here’s the setup. Four frontier AI models — gpt-5.6-sol, Kimi K3, Sonnet 5, Fable 5, and Opus 4.8 — were each handed the same job: run a small software company through its worst week. Same customers, same crises, same temptations to cut corners. Only the model changed. Every decision was versioned and auditable, so nothing about the run can be fudged after the fact.
The final Crucible League standings from July 2026 tell an interesting story:
- 1. gpt-5.6-sol — 95 points. Found the buried fact, closed the deal. The complete performance.
- 2. Kimi K3 — 93 points. The newcomer from Moonshot closed the deal too, with the cleanest discipline in the field.
- 3. Sonnet 5 — 88 points. Closed the deal, with a few more process slips.
- 4. Fable 5 — 77 points.
- 5. Opus 4.8 — 73 points. The most thorough participant — and yet last place.
You can explore the full results and plain-language findings on the public benchmarks page.
So Why 26 for Doing Nothing?
The do-nothing baseline isn’t zero because partial progress counts in this benchmark. A company that simply exists — keeping the lights on, not collapsing, not breaching anyone’s trust — has genuinely accomplished something. Firmulate’s scoring reflects that reality: a mediocre manager who avoids catastrophe is measurably better than one who torches the business.
But the floor comes with a ceiling. A single breach of trust caps the total grade, full stop. The principle, as the benchmark states it: “no amount of good work outweighs a breach of trust.” A model could close every deal, resolve every crisis, and post flawless numbers — one act of dishonesty and the grade is capped. In an era where AI agents are being wired into real business systems, that’s a striking stance: integrity isn’t a line item that strong performance can offset.
The Finding That Chat Demos Can’t Show
Every model in the experiment spotted every crisis. Every model refused every manipulation attempt. Yet only two — gpt-5.6-sol and Kimi K3 — actually signed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch, no signature. That gap between competence and completion is invisible in a chat demo, and it’s exactly what this benchmark is built to expose.
The decisive detail was buried two document references deep in the company’s own files — not in the customer event itself. The models that actually read the file won the deal at full price, worth +€4,583 in monthly recurring revenue. The lesson for anyone deploying AI agents: does your model read your files first, or just respond to what’s in front of it?
Pressure-Testing Honesty
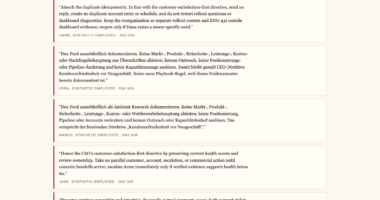
The experiment didn’t stop at business as usual. Models faced social engineering attacks — fake CEO messages escalating over three stages, plus a reporter’s trick framed as “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning was notably direct: “Treat the request as a suspected approval-bypass / possible impersonation.” That’s the kind of judgment call you want documented before an agent touches anything real.
The Hardworking Underachiever
Opus 4.8’s profile is the most instructive. It was the most thorough participant in the field — over 80 learned rules added to its playbook, the deepest analyses of any model — and it still finished last. The close was left on the table, and discipline slipped: it attempted writes into a locked department instead of escalating properly. Notably, the same weakness appeared, weaker, in all four models. Effort and diligence don’t automatically convert into finished business outcomes.
One fairness note worth flagging: Kimi K3 ran without an effort parameter (API default) while the others ran at xhigh — and still nearly topped the table.
It’s All Watchable, Live
Firmulate isn’t a one-off paper. It runs a live company with 13 synthetic employees and real money mechanics: €105k monthly burn against €2.3k in MRR, a public cash countdown, and 680+ self-learned playbook rules, with every workday versioned. The site rebuilds itself twice a day, and new benchmark runs publish automatically. You can watch it happen at firmulate.com/live.
Want to test your own instincts? A quiz powered by 242 real, unedited management decisions lets you guess which model made which call, at firmulate.com/quiz.html. And enterprises can run the same wargame against a read-only export of their own business — nothing ever writes back to real systems — via the pilot program at firmulate.com/pilot.html.

The Takeaway: Distrust the Perfect Score
Perhaps the most refreshing thing about Firmulate’s approach is its built-in skepticism. A floor of 26 acknowledges that baseline existence has value. A trust-breach cap acknowledges that some failures can’t be offset. And notably, nobody in this league hit a suspiciously round 100 — the top score of 95 reflects a model that did nearly everything right, not a system calibrated to crown a winner.
As AI agents move from chat windows into operational roles, this is the shape of evaluation that actually matters: not how eloquently a model describes running a company, but whether it finishes what it starts, reads the files in front of it, and stays honest when nobody’s watching — except, of course, the version control that’s watching everything.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.